PPO vs DPO
A short note on PPO and DPO, two ways to align a model's responses with human preferences.
Both methods aim to better align the model's responses with user's preferences.
-
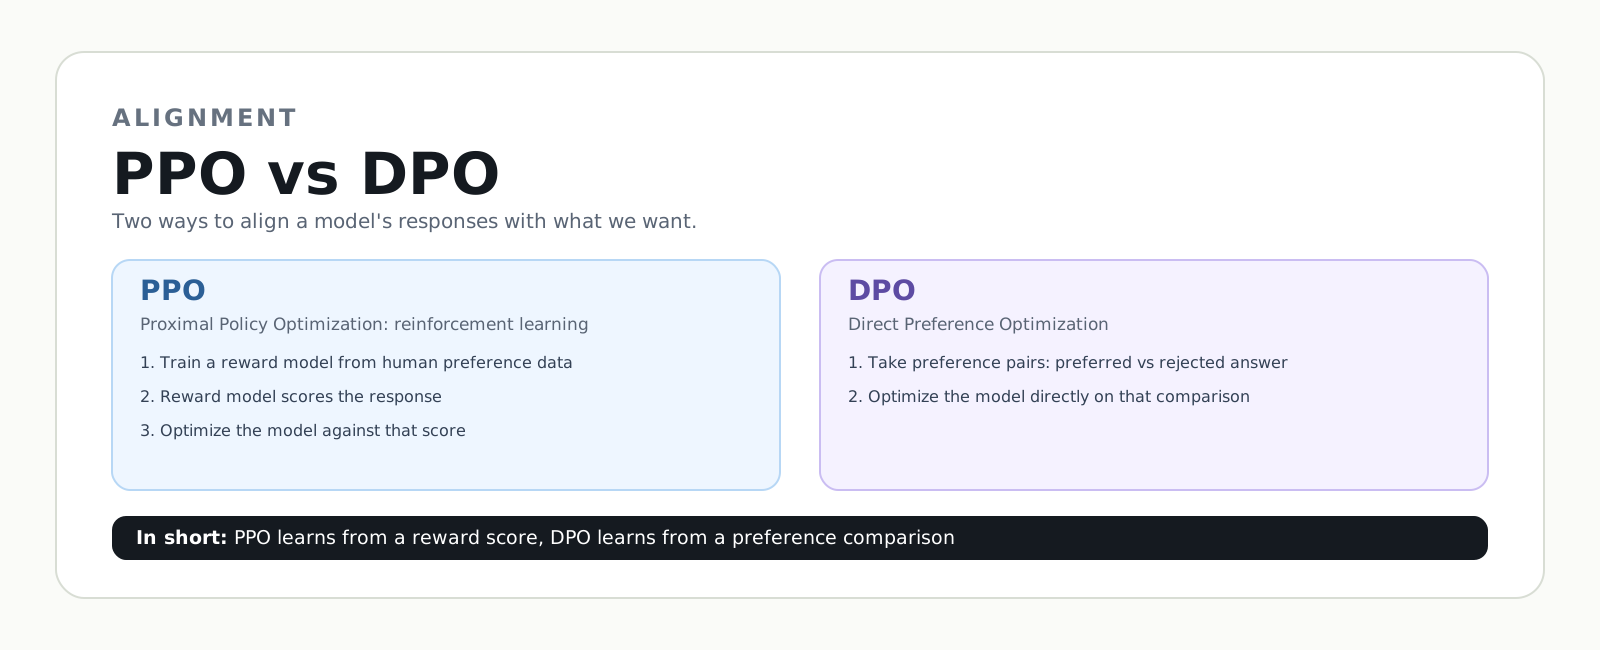
PPO (Proximal Policy Optimization) is a traditional reinforcement learning approach. First, we train a reward model using human preference data. Then we use the reward model to score the model's responses and optimize the model.
-
DPO (Direct Preference Optimization) directly uses preference pairs, where each pair contains a preferred answer and a rejected answer, to optimize the model.
PPO learns from a reward score, while DPO learns from a preference comparison.