ReLU, Neural Nets, and Backpropagation
A compact sketch of ReLU activations, neural network structure, and backpropagation flow.
This sketch is a compact overview of the pieces I want visible when thinking about basic neural networks: layered structure, ReLU activations, the forward pass, loss calculation, and how backpropagation pushes gradients back through the model.
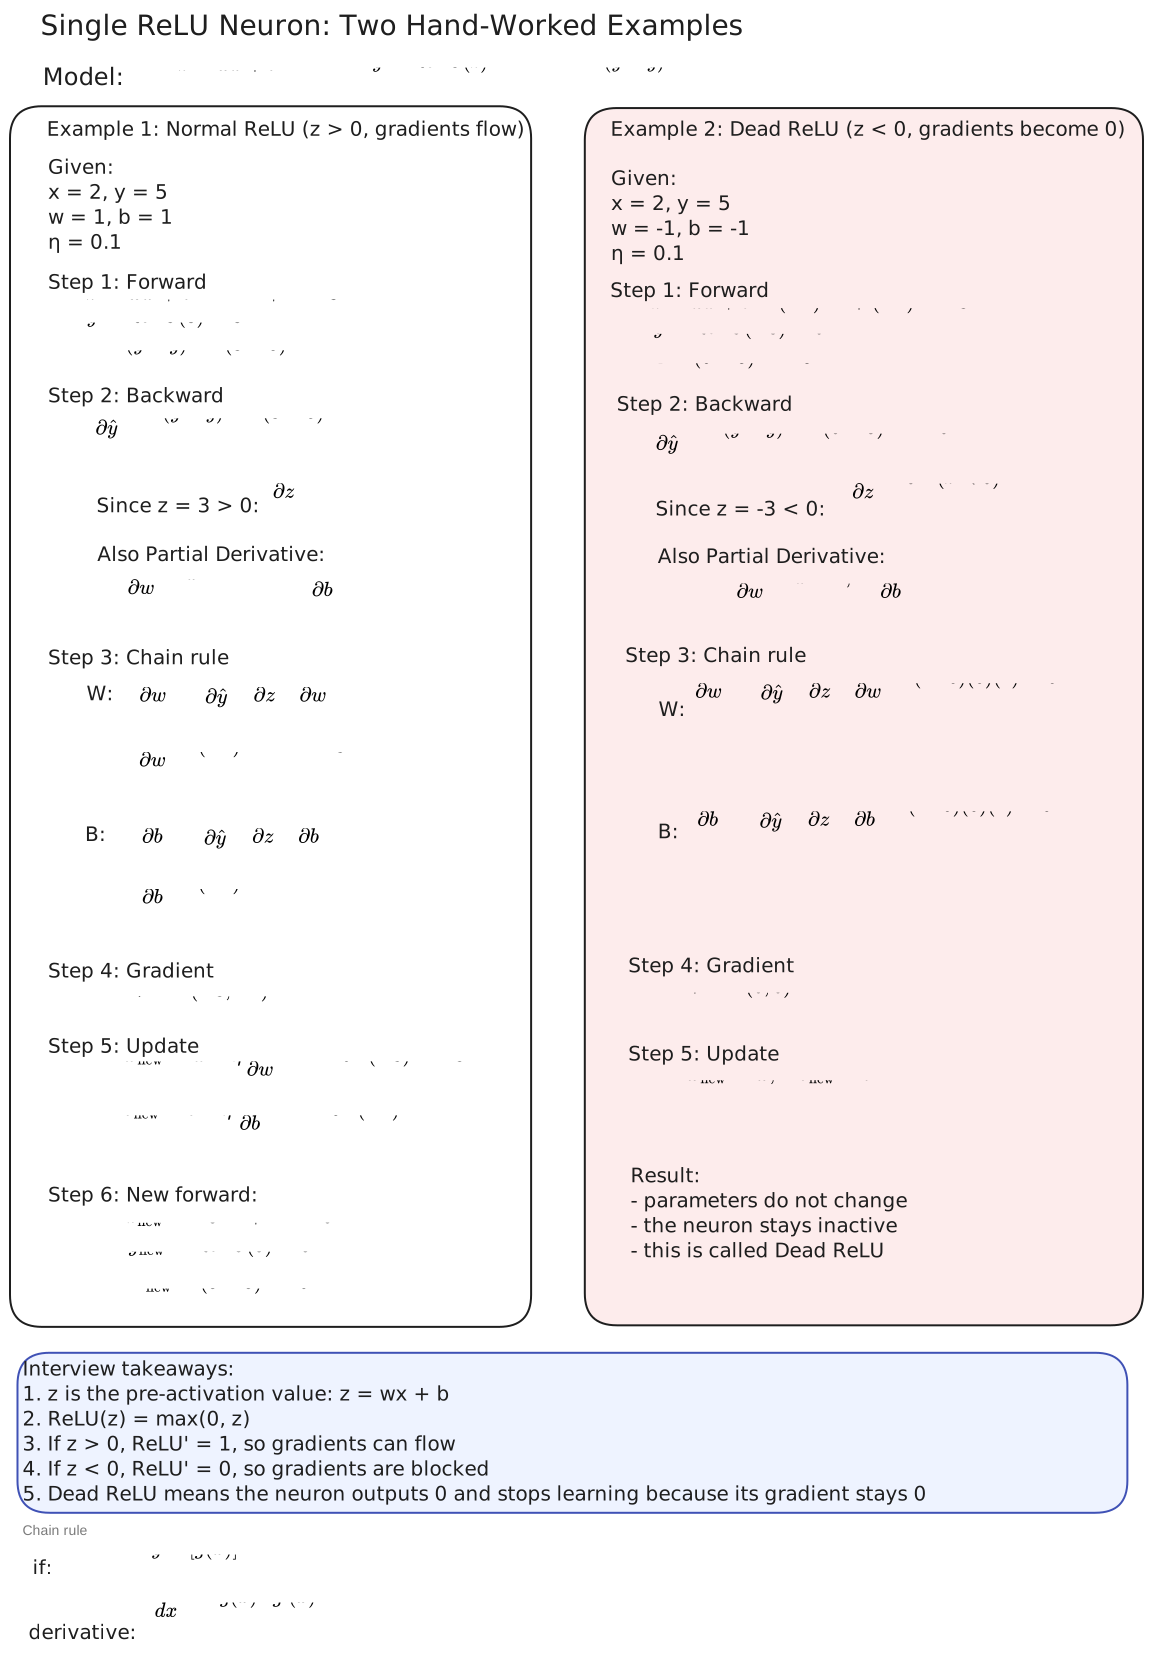
What It Covers
- how a simple feedforward neural network is organized
- where ReLU sits in the forward pass
- how activations move layer by layer toward an output
- how loss connects to gradient flow during backpropagation
- a high-level mental model for parameter updates
It is the kind of note I want nearby before going deeper into implementation details, training behavior, or optimization tradeoffs.